AI projects do not reach production simply because GPUs have been delivered and mounted in a rack. The compute nodes, network fabric, storage, operating systems, drivers, orchestration platform, security controls and support model must operate as one verified infrastructure stack. A weakness in any layer can reduce performance, interrupt training, delay inference services or leave expensive resources underused.
Gatti Services delivers end-to-end AI infrastructure deployment for enterprises, cloud and colocation providers, research organizations and operators of GPU-dense data centers. The work connects physical hardware installation with logical cluster bring-up, integration, commissioning, benchmarking and ongoing operations. Instead of handing customers a collection of disconnected components, Gatti helps build a production-ready environment designed around the applications, models, data and business outcomes the infrastructure must support. A key objective is scalability without losing configuration control.
This is a practical deployment service for artificial intelligence and high-performance computing environments. It covers the work required to turn servers, GPUs, networking, storage and platform software into a stable system that developers, data scientists and operations teams can use with confidence. Every engagement is scoped against the customer architecture, site conditions, workload profile, acceptance criteria and operational responsibilities.
Gatti's wider data center capabilities make that approach different. The same delivery model can coordinate rack and stack, power distribution, structured cabling, containment, direct liquid cooling, firmware and operating system configuration, InfiniBand or Ethernet fabric integration, cluster validation and 24/7 support. This reduces gaps between facilities, hardware, networking and software teams at the point where deployment risk is usually highest.
From Installed Hardware to Production-Ready AI Infrastructure
AI infrastructure is the complete technology foundation used to develop, train, fine-tune, serve and manage machine learning models. At the core is accelerated compute: GPU servers or other processing systems able to run highly parallel workloads. Around that compute layer sit high-bandwidth networks, fast data storage, management networks, scheduling and orchestration tools, observability, identity services, security controls and the software frameworks used by AI applications.
The architecture must reflect the work it is intended to run. Large-scale training depends on sustained collective communication between GPUs, predictable access to training data and reliable checkpoint writes. Distributed inference may prioritize latency, availability, model loading, autoscaling and isolation between services. Analytics, simulation and deep learning research can create different demands again. The best infrastructure is therefore not the platform with the longest product list; it is the one whose compute, data and operational layers have been designed and validated together for the target use cases.
A successful AI infrastructure deployment creates a controlled path from bare metal to production. Hardware is inventoried and verified. BIOS, BMC and firmware settings are aligned. The operating system, GPU drivers and runtime are installed. Network interfaces and fabric paths are configured. Storage is mounted and tested. Cluster resources are exposed to the selected scheduler or container platform. Monitoring, access, documentation and escalation procedures are prepared. The entire stack is then tested under conditions that resemble the workloads it will support.
End-to-End AI Infrastructure Deployment by Gatti Services
Gatti can support the full infrastructure lifecycle from data hall readiness to production handover. The exact scope may begin with a new build, an expansion of an existing GPU cluster, a technology refresh or the logical deployment of hardware that another party has already installed. Each project is organized around clear ownership boundaries so that customer teams, OEMs, platform vendors and Gatti engineers understand who is responsible for each component and acceptance test.
The work begins with discovery. Gatti reviews the intended AI workloads, scale, model types, data flows, availability targets, facility constraints and operating model. Rack elevations, bills of materials, network topology, power design, cooling capacity, storage architecture and software requirements are compared with the planned deployment. The team identifies dependencies, unresolved interfaces and long-lead risks before they affect the schedule.
For on-premises and colocation environments, readiness includes more than available rack units. GPU systems can create concentrated power and thermal loads, while scale-out networks require precise port maps, transceiver choices and cabling paths. Liquid-cooled platforms may require CDU commissioning, coolant validation and coordinated handling of primary and secondary loops. The deployment plan brings these physical requirements together with logical configuration, change windows, access controls and acceptance criteria.
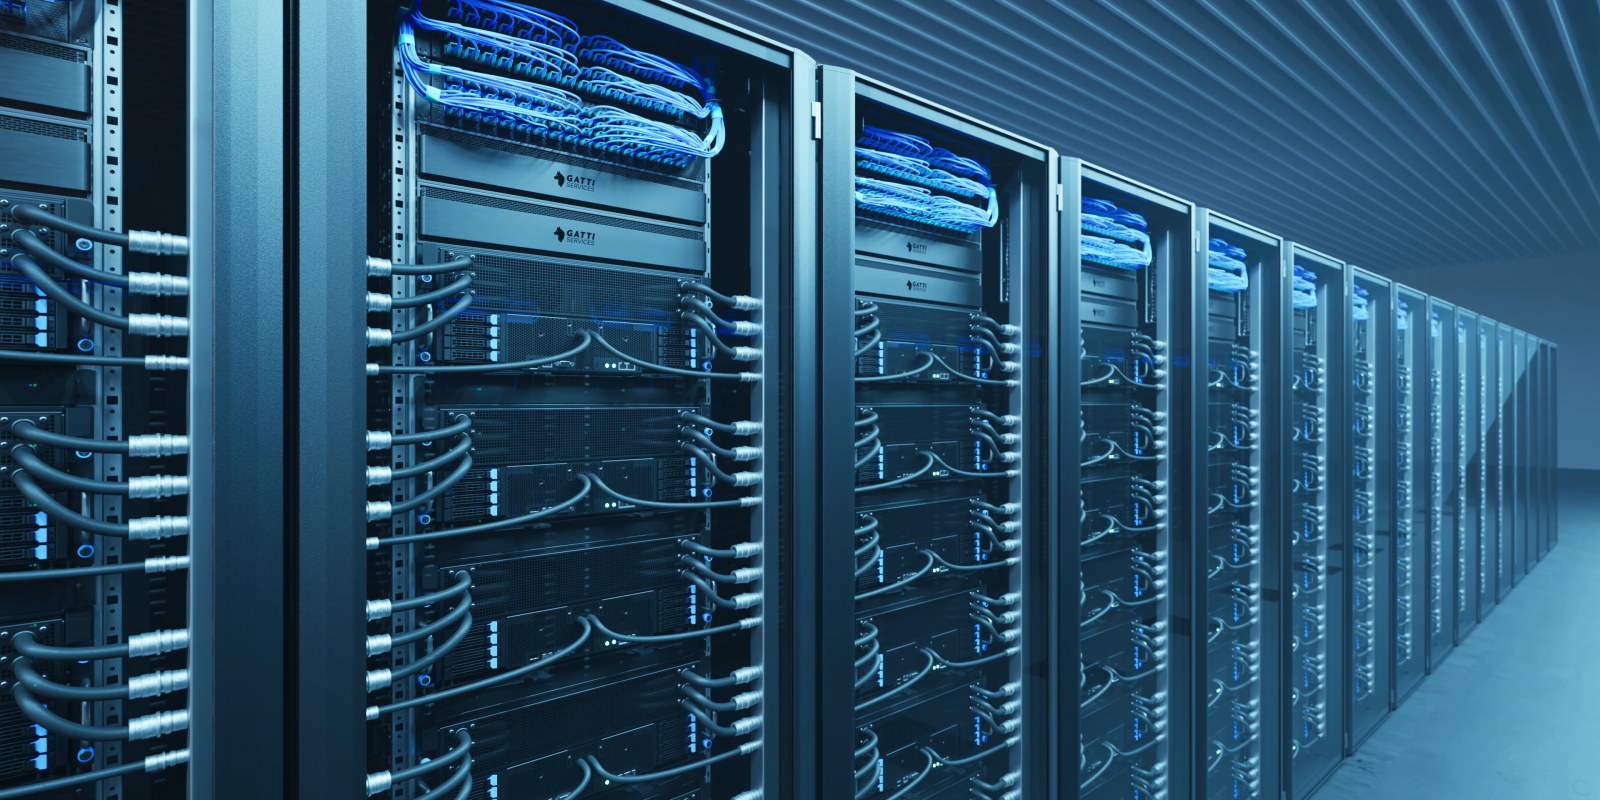
Where required, Gatti installs the physical foundation through its Data Center Design & Build and Physical Hardware Installation services. Engineers rack and stack compute, storage and network hardware; install and label copper and fiber connections; integrate transceivers; coordinate containment; and sequence power. Direct liquid cooling integration can include quick-connect manifold handling, CDU commissioning and mechanical deployment activities within the agreed design.
This joined-up approach is important in GPU-dense environments. A logical deployment cannot be stable if a server is connected to the wrong fabric port, an optical link exceeds its loss budget, a redundant power feed is incomplete or cooling capacity changes across the rack. Physical records, asset data and port mappings become inputs to the cluster configuration rather than separate documents produced after the fact.
Logical bring-up starts by creating a known configuration baseline. Gatti can support BIOS and BMC configuration, firmware alignment, out-of-band management checks, operating system provisioning and early dead-on-arrival screening. Settings are applied against the approved OEM and platform guidance, then recorded so that deviations can be found later.
The software baseline may include Linux, GPU drivers, CUDA for NVIDIA environments or ROCm components for supported AMD environments, network drivers, OFED or vendor fabric software, container runtimes and required system libraries. Versions are treated as a compatibility matrix, not installed independently. Driver, firmware, kernel, runtime and framework combinations must be aligned because a cluster that boots successfully can still fail under distributed processing.
Each GPU and node is checked before resources are released to users. Inventory, device visibility, memory, PCIe paths, error counters and health data provide the first overview. On NVIDIA platforms, DCGM acceptance procedures can be included; equivalent vendor-appropriate diagnostics can be selected for other systems. Burn-in and hardware stress testing help expose intermittent faults, thermal instability and weak components before customer training jobs carry the discovery cost.
Within a server or rack-scale system, technologies such as NVLink and NVSwitch may provide high-bandwidth GPU-to-GPU communication. These scale-up paths are distinct from the scale-out fabric connecting nodes. Gatti validates the relevant topology and system configuration at each layer, helping ensure that applications see the GPUs and communication paths the architecture was designed to provide.
Distributed AI performance depends heavily on networking. Gatti supports leaf-spine fabric deployment, InfiniBand topology validation and high-performance Ethernet environments, including RDMA over Converged Ethernet where it is part of the approved design. Management, storage and compute fabrics are configured according to their separate purposes, with addressing, VLANs, routing, MTU, quality-of-service and redundancy settings controlled as required.
For NVIDIA-based clusters, this can include Quantum InfiniBand or Spectrum-X Ethernet architectures. The correct solution depends on the platform, scale, tenancy model and customer standards. InfiniBand and RoCE are not interchangeable labels: they use different operational models and require the appropriate switches, adapters, configuration and monitoring. Gatti works to the selected reference architecture rather than applying generic settings to every network.
Validation checks topology, link state, bandwidth, latency and communication consistency. NCCL sweeps and workload-relevant collective tests can reveal weak links, rail imbalance or configuration differences that basic ping tests will not find. The objective is not simply to prove that packets move; it is to show that the fabric can support the communication patterns used by distributed training and inference workloads.
Training infrastructure needs reliable access to large datasets and predictable checkpoint performance. Inference systems need fast model distribution and controlled access to production data. Gatti coordinates the storage layer with compute and networking, validating mounts, paths, permissions, throughput, latency and resilience against the agreed architecture. Parallel file systems, object storage, block storage and local NVMe tiers may all have roles, but their design must match the workload and lifecycle of the data.
Testing should cover more than a single peak number. Metadata operations, concurrent reads, checkpoint writes, recovery behavior and sustained transfer rates can affect real applications. Where the selected hardware and software stack supports technologies such as GPUDirect Storage, integration also requires compatible drivers, file systems and configuration. Gatti can validate the infrastructure interfaces while the customer or storage product owner retains responsibility for application-specific data engineering unless that work is explicitly included.
Compute becomes useful when workloads can request and release resources predictably. Depending on the customer environment, the orchestration layer may use Slurm, Kubernetes or another approved platform. GPU resources must be discovered correctly, assigned to jobs or containers and isolated according to the operating model. Node labels, partitions, queues, device plugins, container runtimes, images, quotas and scheduling policies are configured within the agreed scope.
A platform for AI is more than a control plane. It needs a reliable relationship with identity, networking, storage, monitoring and change management. Gatti can deploy or integrate the infrastructure components that expose cluster resources to the platform, then test representative jobs. This provides a stable base for open and commercial MLOps tools, model registries, experiment tracking, CI/CD pipelines and application services managed by the customer's developers or a specialist platform team.
Production environments need evidence of how systems behave over time. Monitoring can collect GPU health, utilization, temperature, power, network counters, storage performance and platform status. Alerts and dashboards are aligned to support responsibilities so that an incident reaches the team able to act. Baselines captured during commissioning provide insights that help operations learn what normal workload variation looks like and distinguish it from degradation.
Security is built through multiple controls and operating practices: protected BMC and management access, network segmentation, role-based access, logging, controlled credentials, hardened configuration, patch procedures and documented change. These measures support the customer's broader governance and compliance program, but infrastructure deployment alone does not certify an AI model, remove application risk or replace organizational AI governance. Responsibilities for model data, privacy, safety, access approval and regulatory assessment must remain explicit.
A Structured AI Infrastructure Deployment Process
Gatti uses a staged deployment process so that problems are isolated early and acceptance is based on evidence. The detailed runbook changes by project, but the following sequence provides a practical guide.
1. Define the target state
The customer, Gatti and relevant vendors agree the workload goals, capacity, architecture, support model and definition of done. This includes the number and type of GPUs, expected network topology, storage paths, platform choice, security requirements, performance thresholds and documentation deliverables. Assumptions are recorded before work begins.
2. Confirm site and hardware readiness
The team verifies space, power, cooling, cabling, asset inventory, firmware availability and management access. Missing components, damaged hardware and inconsistent bills of materials are addressed before logical configuration depends on them. This stage may include rack inspection, power load checks, containment audits and coolant or airflow validation.
3. Establish a controlled configuration baseline
BIOS, BMC, firmware, operating system, drivers and fabric software are aligned to the approved matrix. Repeatable automation is used where suitable, while exceptions are tracked. Secure access and configuration records are created from the start rather than added after production handover.
4. Bring up compute, networking and storage in layers
Individual nodes are validated before the scale-up and scale-out domains are tested. Management connectivity, GPU visibility, network links and storage access are checked separately, then together. This layered method helps locate a fault in the right system instead of treating every failed workload as an application problem.
5. Integrate orchestration and platform services
Resources are presented to the selected scheduler or container platform. Authentication, queues, quotas, device allocation, images and operational tools are integrated as agreed. Representative applications are used to confirm that users can get the intended resources without bypassing governance or creating uncontrolled configuration drift.
6. Benchmark, stress and validate
Gatti's AI Cluster Benchmarking & GPU Infrastructure Integrity service can combine thermal validation, power load testing, cable verification, hardware stress testing, bandwidth and latency analysis, NCCL validation, HPL benchmarking and GPU workload simulation. No single benchmark proves production readiness. Results are interpreted together against topology, workload and environmental data.
7. Remediate, retest and document
Failed components, weak links, firmware mismatches and configuration issues are corrected through an agreed defect process. OEM RMA coordination and hot-spare rotation can support continuity during early deployment. Tests are repeated after changes, with outcomes, exceptions and residual risks documented.
8. Handover into production operations
The final handover includes as-built architecture, asset and port records, configuration baselines, test results, known exceptions, access procedures, escalation paths and support responsibilities. Operations teams receive an environment they can run, not only a statement that installation is complete.
Validation That Reflects Real AI Workloads
AI systems can pass component checks and still perform poorly at cluster scale. A server may report healthy GPUs while a fabric link creates collective-communication stragglers. Storage may reach a strong sequential read rate but stall during concurrent checkpoint writes. Cooling may remain within limits at idle and become asymmetric during a long training run. Production-like validation is designed to find these interactions.
Gatti combines infrastructure integrity testing with workload-relevant benchmarking. HPL can provide insight into compute performance, while NCCL tests evaluate collective communication on supported NVIDIA environments. DCGM diagnostics can assess GPU health and system readiness. Network bandwidth and latency tests, thermal observation, power analysis and storage testing add the context needed to understand why a result is strong or weak.
Acceptance thresholds should come from the approved architecture, vendor guidance and customer service objectives. Benchmark results are therefore not presented as universal scores. A large research cluster, an enterprise inference platform and a multi-tenant AI cloud may use different pass criteria. The important outcome is a repeatable baseline that shows the infrastructure can sustain the intended work and gives support teams useful evidence when performance changes later.
Designed for Training, Inference and Mixed AI Environments
AI model training
Training large models can occupy many GPUs for long periods. Jobs need consistent compute, high-bandwidth GPU communication, reliable dataset access and fast checkpoint storage. A single unstable node may waste substantial time across the entire allocation. Deployment for training therefore emphasizes topology consistency, sustained thermal and power behavior, fabric performance, scheduler reliability and failure recovery.
Inference infrastructure serves trained models to users, products and business processes. It may prioritize latency, availability, model loading, observability, scaling and isolation. The deployment must coordinate GPU capacity with traffic patterns, application frameworks, security controls and release processes. Testing should include realistic request behavior and failover expectations, not only maximum processing throughput.
Many organizations run mixed environments that support analytics, machine learning research, fine-tuning, simulation and production services on the same platform. Resource policies must prevent one workload from starving another. Storage and networking need predictable performance, while developers need access to approved tools and frameworks. Gatti helps build the infrastructure and operational controls that make this shared use manageable at scale.
On-Premises, Colocation and Hybrid Cloud Integration
Organizations choose on-premises or colocation AI infrastructure to gain control over performance, data location, cost, hardware selection and operational policy. Others combine dedicated GPU resources with public cloud services. Gatti can deploy the data center and cluster foundation for these environments and coordinate the interfaces to external platforms within the agreed architecture.
Hybrid integration may include secure connectivity, identity boundaries, data transfer paths, monitoring and workload orchestration across environments. If data pipelines exchange information with services such as Databricks or Snowflake, or if model lifecycle tools run in the cloud, the network, access and data-governance requirements should be designed explicitly. Gatti's role is to make the underlying infrastructure and integration points reliable; ownership of the application, data platform and MLOps process remains defined by scope.
This clarity also improves cost management. Dedicated infrastructure has different pricing drivers from consumption-based cloud services: GPU and server hardware, racks, power, cooling, optics, storage, licenses, engineering, spares and support coverage all matter. Gatti develops deployment solutions around the customer's real needs rather than assuming that every enterprise should build the same stack.
Security, Compliance and AI Governance by Design
Infrastructure security begins below the application layer. Management controllers, switches, storage systems and orchestration platforms all create privileged access paths. A secure deployment limits those paths, separates management and workload traffic, protects credentials, records administrative activity and maintains approved firmware and software baselines. Physical access, asset control and accurate documentation support the same objective.
Gatti's service delivery is backed by independently audited ISO 9001:2015 quality management and ISO 27001:2022 information security management certifications issued by DNV. These certifications support disciplined processes and information-security controls around service delivery. The exact compliance requirements for the customer environment still depend on its sector, location, data, workloads and regulatory obligations.
AI governance extends beyond infrastructure. It includes decisions about training data, model behavior, explainability, human oversight, privacy, security and acceptable use. Infrastructure can provide access controls, logs, isolation, repeatable environments and traceability that help governance work, but it cannot make those organizational decisions. Gatti coordinates the technical foundation with the customer's governance owners so that responsibilities remain clear throughout the lifecycle.
Scalable Operations After Deployment
Production handover is the beginning of the operating lifecycle. New models, updated frameworks, security patches, capacity growth and hardware failures continuously change the environment. A scalable support model needs monitoring, controlled change, incident management, spare strategy, vendor escalation and technicians who understand both the data center and the GPU platform.
Gatti provides Smart Hands Services and Remote Hands Support across hardware, networking, cooling and platform environments. Coverage models include 24/7, seven-day and 8/5 support tailored to operational needs and service-level requirements. On-site engineers can perform physical intervention, while remote specialists support diagnostics, IPKVM-assisted work, firmware management, fabric issues and OEM coordination through a unified workflow.
This model is already applied in demanding AI and HPC operations. Gatti's German Datacenter Association profile states that the company manages more than 100,000 GPUs across several European sites, supported by in-house engineers in Germany, the United Kingdom, the Nordics and the Philippines. Gatti also supports Northern Data Group through a multi-site strategic partnership spanning Europe and the United States. These are practical proof points of experience operating beyond a single installation or one-time deployment.
Standardized runbooks, configuration baselines and acceptance data help the service scale across locations. Central teams get a consistent overview, while local engineering can respond to the physical conditions of each site. This is especially valuable for enterprises and cloud providers building new capacity in phases or expanding an established platform into additional data centers.
Why Organizations Choose Gatti Services
One accountable delivery model
Gatti can connect data center design, physical installation, power, cooling, cabling, hardware commissioning, logical deployment, benchmarking and support. Fewer boundaries mean fewer opportunities for a critical issue to sit between suppliers.
GPU and AI infrastructure specialization
The teams work with GPU-dense environments, including NVIDIA Hopper and Blackwell platforms, B200/B300 and H100/H200 systems, as well as NVL72 rack-scale systems such as GB300 or soon Vera Rubin architecture. Deployment is designed around AI and HPC behavior rather than adapted from a generic enterprise server rollout.
Vendor-neutral integration
Customers are not forced into a single product model. Gatti works across NVIDIA, AMD and major OEM ecosystems, integrating the approved technologies, components and platforms into a coherent architecture. Recommendations are based on compatibility, operational requirements and the customer's chosen standards.
Validation before production
Benchmarking, burn-in, DOA screening, network validation, thermal analysis, power testing and production-like simulations reduce the risk of discovering infrastructure faults during valuable workloads. Results create a measurable baseline for future management and support.